Your brain runs on twenty watts.
That is not poetic license or a rough metaphor. Your nervous system, with its 86 billion neurons and hundreds of trillions of synaptic connections, draws roughly the same electrical power as two common household LED bulbs. It can recognize a childhood friend you have not seen in twenty years, master a complicated espresso machine on the first attempt, navigate an unfamiliar subway station without bumping into a soul, and formulate an original thought it has never articulated before, all while sipping less current than an idling laptop charger.
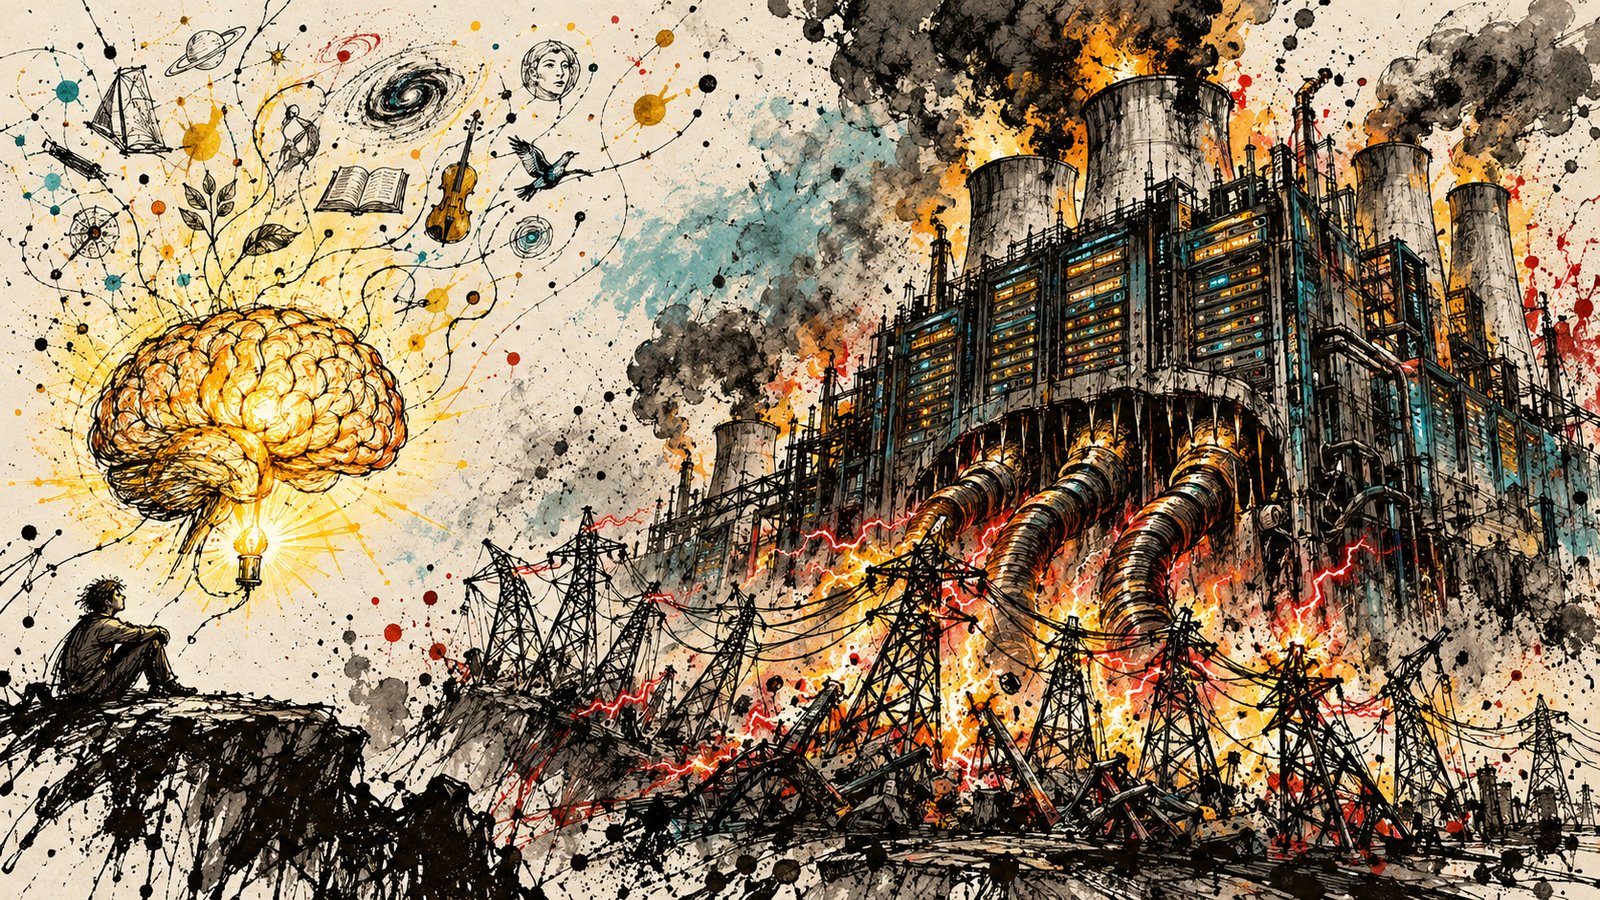
Now look at the artificial alternative. PNAS reports that training GPT-3 consumed as much electricity as powering 120 American homes for an entire year, while training GPT-4 required an estimated fifty times more energy than its predecessor. Today, the global data center electricity demand powering frontier AI models is measured in hundreds of terawatt-hours, expanding at a pace that keeps utility directors and regional grid operators awake at night.
We have engineered synthetic intelligence that demands a dedicated power plant to run. Biology engineered minds that run on the power of a hallway nightlight.
Something fundamental is broken in how we build computers. And a determined cadre of electrical engineers, neuroscientists, and semiconductor architects are convinced they know exactly what it is.
The Architecture That Moore Forgot#
The crisis facing modern artificial intelligence is not that our silicon is slow. It is that our machines are fundamentally organized the wrong way.
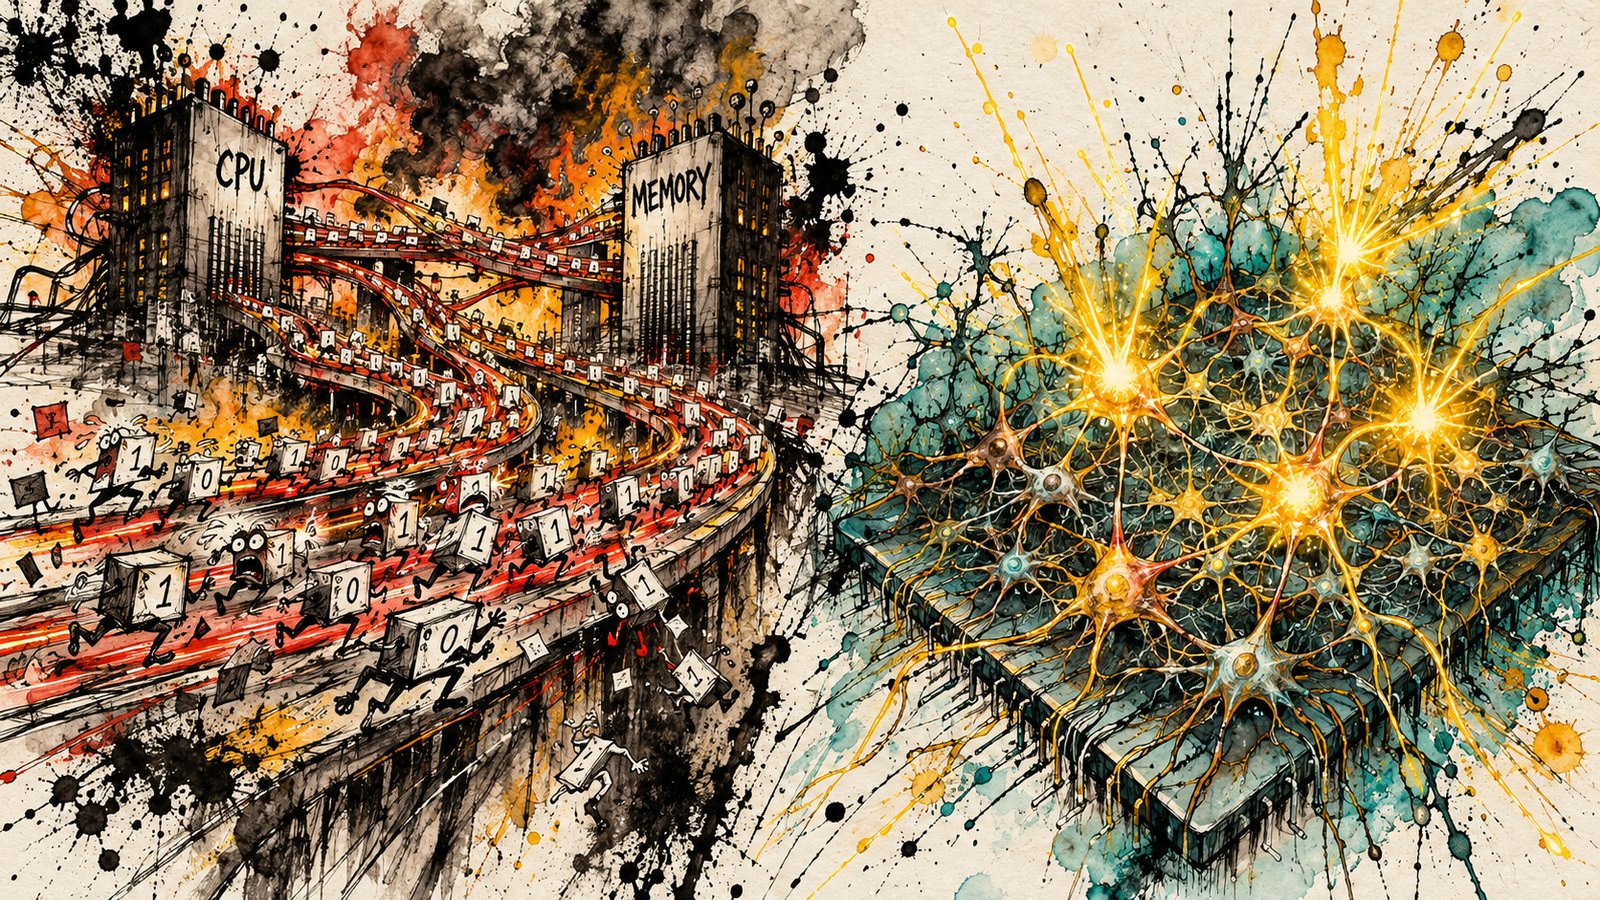
Nearly every digital device you have ever touched obeys a shared seventy-year-old blueprint. Memory sits in one physical location. The central processor sits in another. Whenever the compute core needs to perform an operation, it must request data across a bus, wait for the bytes to travel, execute the arithmetic, and transmit the output back to storage. This is the classic Von Neumann architecture, and it has anchored commercial computing since the 1940s.
The real choke point in modern computing is not raw clock speed. It is the crushing energy cost of ferrying data between storage registers and arithmetic logic units. Hardware engineers call this the “memory wall,” and it grows steeper every year as transistor densities outstrip interconnect bandwidth.
For AI workloads, which are essentially staggering exercises in multiplying massive matrices and shuffling billions of weights, the memory wall accounts for the vast majority of all consumed power. When modern GPU clusters run frontier inference, most of the electricity burned and heat radiated goes to moving bits across traces, not to performing mathematics.
Human biology never made that mistake. In the nervous system, memory and computation happen in the exact same physical structure. The synapse that stores an association is the identical biological mechanism that calculates with it. There is no external memory bus, no hierarchical cache penalty, and no round-trip data movement tax. The calculation is the storage.
That observation is the foundation of neuromorphic computing. Caltech pioneer Carver Mead coined the term in the late 1980s, asking a radical question: what if we designed silicon to mimic biological neural structures directly, instead of forcing Von Neumann machines to run faster? His early lab demonstrations produced silicon retinas and analog electronic cochleas: physical sensors that digested signals the way sensory biology does, rather than slicing reality into synchronized clock cycles.
Four decades later, Mead’s theoretical question has evolved into hardware rolling off real fabrication lines. In a comprehensive review published in Nature, Dhireesha Kudithipudi and colleagues mapped the rapid scaling of neuromorphic architectures, demonstrating how on-chip memory and event-driven computation are breaking past the limits of conventional digital designs.
How Neuromorphic Silicon Actually Computes#
A conventional digital microprocessor marches to the drum of an internal clock. Every calculation executes at a rigid, predetermined cadence, cycling billions of times each second whether there is meaningful information to evaluate or not. The chip draws continuous baseline power. Even idle clock cycles burn juice.
Neuromorphic silicon abandons the clock entirely. It operates on asynchronous events: spikes.
Thousands or millions of microscopic artificial neurons sit inside an on-chip network, bound together by synthetic synapses. Each neuron maintains an internal electrical potential. When incoming signals push that potential across an engineered threshold, it fires a spike: a discrete, microscopic voltage pulse transmitted to downstream neurons.
Between spikes, the circuit goes dark. It draws virtually zero current.
This is not a software simulation or a mathematical emulation running on conventional logic gates. The silicon physically embeds spiking neural networks (SNNs) in hardware. The synthetic neurons are dedicated circuits; the spikes are physical voltages; and the synaptic weights update locally through physical state changes like memristors or phase-change materials, rather than cycling through software backpropagation on a graphics card.
The result is a processor that remains virtually inert when nothing is changing, waking up in microsecond bursts only when an event demands attention. Audio wake-word monitoring, gesture recognition, vibration tracking, and robotic vision are naturally event-driven tasks. Neuromorphic hardware treats them as nature does: spending energy only when the world actually moves.
The Evidence on the Bench#
The empirical benchmarks emerging from recent neuromorphic deployments are impossible to ignore.
In a landmark paper published in Science, Dharmendra Modha and the IBM Research team unveiled NorthPole, a brain-inspired chip that demonstrated that hardware organization matters far more than shrinking transistor nodes. On standard computer-vision benchmarks, NorthPole delivered superior classification throughput at a fraction of the energy consumption of conventional accelerators, running five times faster than comparable systems. Modha summarizes the philosophy bluntly: architecture trumps Moore’s Law. How you organize data flow matters far more than how small you etch your gates.
Intel’s Loihi 2 processor, released to academic and industrial research labs, packs over one million artificial neurons and 120 million synapses onto a single die. It achieves tenfold throughput gains over its first-generation predecessor. Satellite communications researchers have even deployed Loihi directly into orbit, demonstrating cognitive software-defined networking running on an in-orbit spiking processor.
At UC Santa Cruz, professor Jason Eshraghian’s Neuromorphic Computing Group made history by deploying a full large language model directly onto neuromorphic hardware. In their research on Scalable MatMul-free Language Modeling and Neuromorphic Principles for Efficient Large Language Models on Intel Loihi 2, the team adapted a billion-parameter language model to eliminate matrix multiplication entirely. By replacing dense matrix math with ternary weights and stateful, low-precision spiking arithmetic, the system generated roughly 100 tokens per second while consuming just 2.5 watts of power on Loihi 2. A billion-parameter language model operating on the power budget of a holiday string light is an architectural sea change.
Patent filings reflect this acceleration. Industrial patent databases logged a 401% surge in neuromorphic chip intellectual property filings in 2025 alone. Commercial market forecasts project the sector will expand from $3.56 billion in 2025 toward $28.74 billion by 2034, registering an annual compound growth rate exceeding 26%.
The debate is no longer whether biological silicon works. The question is which real-world systems it transforms first.
Robotics: Vision at Microsecond Latency#
Autonomous robotics has an intractable physics problem under conventional computing. A machine must perceive dynamic terrain, plan collision-free paths, and actuate motors in real time, all while carrying a finite onboard battery.
Standard digital cameras record reality in discrete frames, typically 30 or 60 snapshots every second. Between those exposures, the physical world keeps moving. The robot is effectively blind during the shutter interval. Increasing frame rates to capture high-speed motion explodes the data volume, flooding the processor with redundant pixels, overheating onboard compute, and draining the battery in minutes.
Event-based cameras, the modern commercial heirs to Carver Mead’s silicon retina, solve this by redesigning vision from scratch. They do not capture rectangular frames. Every single pixel on the sensor grid operates independently, triggering an electrical spike only when the light intensity hitting that specific coordinate changes.
If a wall sits still, the sensor generates zero data. If a drone darts across the field of view, only the moving edge generates a stream of microsecond-stamped spikes. The sensor has virtually zero motion blur, high dynamic range in blinding sunlight, and orders-of-magnitude lower power consumption.
Recent robotics navigation research highlights the power of this paradigm. In a paper on Real-Time Neuromorphic Navigation, researchers demonstrated TurtleBot rovers navigating cluttered mazes and Bebop2 quadrotors threading through moving gates using neuromorphic event cameras paired with compact edge processors. The drone does not stream video to a cloud data center. It does not wait on wireless latency. It senses, computes, and adjusts its flight path locally within a tiny onboard energy envelope.
Consumer Hardware: Microwatt Edge Intelligence#
This is where neuromorphic engineering moves out of research papers and lands in your pocket.
In late 2025, Dutch semiconductor developer Innatera secured its first major original design manufacturing contract with Xiamen Joyatech (Joya), which manufactures connected consumer products for major global brands. Joya is integrating Innatera’s Pulsar neuromorphic microprocessors directly into consumer electronics, smart home appliances, and health wearables. The Pulsar processor runs spiking networks on silicon to handle voice wake, presence sensing, and bio-signal recognition directly on the device, eliminating the need to transmit private sensor data to remote servers.
Similarly, BrainChip has brought its Akida neuromorphic co-processors into commercial wearables through the AkidaTag reference platform, combining its AKD1500 processor with Nordic Semiconductor wireless silicon to enable always-on acoustic and gesture monitoring on coin-cell batteries.
The architecture inverts the current smart home model. Today, your connected thermostat, smart speaker, and security camera are essentially dumb input terminals broadcasting your private life to corporate server farms. Neuromorphic edge intelligence processes voice commands, footstep acoustics, and glass-break frequencies directly on the sensor at the microwatt level. Nothing leaves your home because the computation is completed where the physics occurred.
The Honest Engineering Caveats#
Neuromorphic computing is not a magic wand that will sweep away data center GPUs overnight. Real engineering bottlenecks remain:
- The software ecosystem chasm: You cannot take an existing PyTorch model trained on graphics cards and compile it straight onto a neuromorphic chip. Spiking neural networks demand fundamentally different training techniques, event-based data encoding, and specialized algorithmic toolchains. The software tooling is easily a decade behind the silicon.
- Dynamic hardware plasticity: Biological brains rewire physical synaptic connections on the fly through neuroplasticity. Commercial neuromorphic silicon, with rare laboratory exceptions, fixes its network topology during manufacturing or compilation. Achieving robust, low-power on-chip learning in volume production remains one of the hardest problems in materials science.
- The biological scale gap: The human neocortex coordinates hundreds of trillions of synaptic junctions. The most ambitious experimental neuromorphic systems today simulate billions. Closing that three-order-of-magnitude gap will require breakthroughs in 3D chip stacking and novel memristive materials.
The Hybrid Machine#
The pragmatic future of computing is not an immediate, scorched-earth replacement of traditional logic. It is architectural convergence.
Your smartphone already balances specialized silicon: general-purpose CPU cores, high-throughput GPUs, digital signal processors, and dedicated neural accelerators. Adding an ultra-low-power neuromorphic co-processor is the logical next step. The CPU handles operating system coordination; the GPU renders graphics; the NPU accelerates dense matrix transforms; and the neuromorphic engine quietly monitors sensory inputs at microwatts, waking up the heavier systems only when genuine novelty occurs.
Biology solved real-time perception and cognition under ruthless metabolic limits millions of years ago. By borrowing nature’s blueprint, we are finally building hardware that makes intelligence sustainable.